
If you stopped working tomorrow, how long would your business keep its promises? Not how long would the servers stay up—how long before a failed payment, urgent support ticket, expiring domain, or customer request needed a decision only you could make?
For a solo founder, that question can sound like a vacation-planning exercise. It is a cash-flow question. A business that depends on its owner being available every day has an invisible operating cost: the possibility that one illness or family emergency interrupts collections, service, or both. You do not need a management layer to fix it. You need to identify what must happen during a two-week absence and make those few things possible without you.
Map the work that cannot wait
Start with the last 30 days, not an imagined catastrophe. Review your support inbox, payment dashboard, bank transactions, uptime alerts, and calendar. Mark every item that required your judgment or access. Then ask which items would have caused a refund, lost customer, service outage, or missed obligation if left untouched for 14 days.
A solo SaaS doing $18,000 in monthly recurring revenue might receive 90 support messages a month. Perhaps 70 are how-to questions that can wait two business days, 15 involve billing changes, and five report broken workflows. The objective is not to arrange coverage for all 90. It is to make sure the handful that can stop a customer from using the product reach someone capable of acting.
Put the time-sensitive work into three buckets:
- Keep the service running: production alerts, failed deployments, expiring infrastructure, and security incidents.
- Keep cash moving: payment failures, invoices, payroll or contractor payments, and tax or filing deadlines.
- Keep promises: urgent support, contractual response commitments, and customer data requests with deadlines.
For each task, record its deadline, the system needed to complete it, and the maximum loss from a two-week delay. Use rough numbers if that is all you have. If an unanswered billing email could delay a $4,000 annual renewal, it deserves more attention than a cosmetic bug report. If a hosting incident could affect every subscriber, it outranks both.
This exercise also reveals work you can remove. A founder who manually approves every routine refund may be creating an emergency where a clear rule would do. A product that requires hand-editing account records for ordinary plan changes has an operational debt, even if the codebase has no obvious technical debt.
Put recurring cash on a calendar
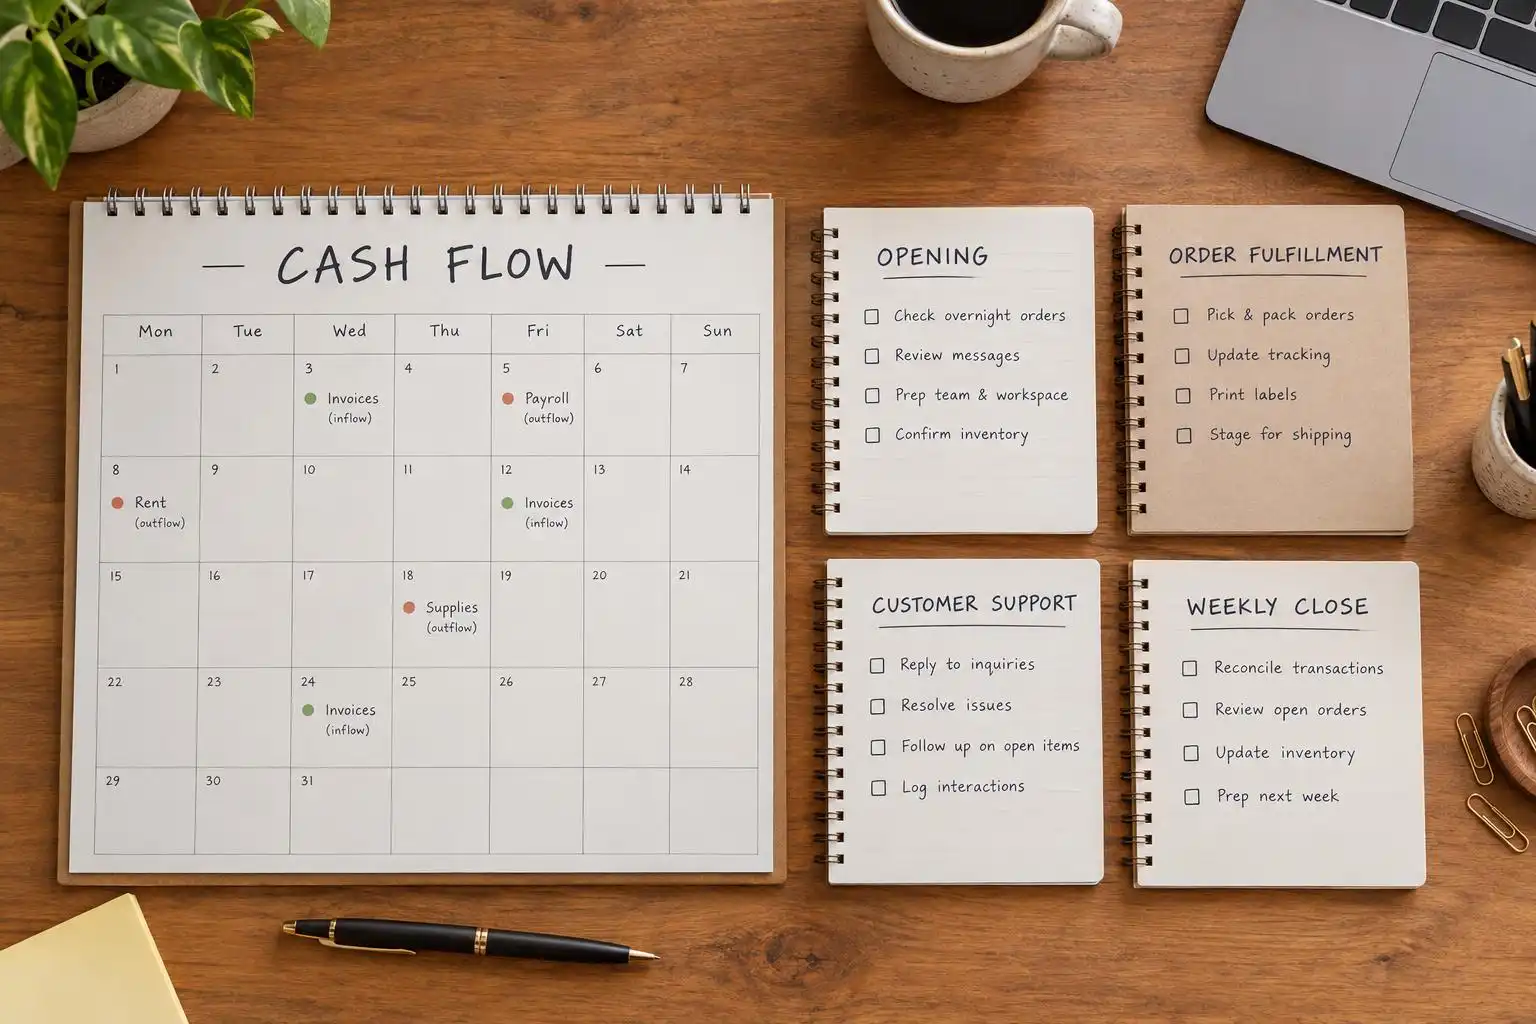
An MRR dashboard is not an absence plan. Open your bank account and list the dates when money actually comes in and goes out. Include card payouts, annual invoices, cloud hosting, software subscriptions, contractor bills, owner draw, debt payments, and taxes. Identify anything that requires you to log in, approve, or transfer funds.
Suppose the company collects $12,000 a month through card payments and another $6,000 through manually issued invoices. Its monthly expenses are $9,000, with $4,500 due in the first week. Two weeks away may barely affect card collections, but one missed invoice and a delayed payout could leave the operating account short at the wrong moment. Profitability does not prevent a timing problem.
Set a minimum operating balance that covers the largest plausible two-week outflow plus an error margin. In that example, if $4,500 in bills could land during the absence, holding $7,000 in the operating account might be a practical floor. This is separate from the company’s longer-term reserve: it is money positioned where automatic payments can use it without an emergency transfer.
Then reduce the number of manual cash events. Send known invoices before their due dates, automate routine billing reminders, schedule predictable transfers where your bank allows them, and maintain a dated list of obligations that cannot be automated. Do not give an assistant unrestricted banking access simply to make this work. The safer first move is to make ordinary payments predictable and leave a documented escalation path for exceptions.
Check annual renewals and domain registrations too. A domain that expires during your absence can create a much larger revenue problem than a late vendor payment. Enable auto-renewal, keep a valid backup payment method, and verify that renewal notices go to an address someone will monitor. Treat critical infrastructure accounts as business assets, not personal inbox housekeeping.
Write the smallest useful runbooks
A 60-page operations manual will go stale. Instead, write one-page instructions for events that are both consequential and plausible. A backup person should be able to read a page, decide whether an issue is truly urgent, and either take a safe action or escalate. They should not have to reconstruct your entire architecture.
Begin with these four runbooks:
- Service outage: where to check status, who hosts what, and when to roll back or contact a specialist.
- Urgent customer issue: what qualifies as urgent, where to find account history, and what can be promised.
- Billing exception: how to confirm a charge or invoice, what can be corrected, and who approves refunds.
- Security concern: how to preserve evidence, restrict access, and contact the right technical help.
Give each page a last-reviewed date. Include exact links and account names, but keep passwords and recovery codes in a password manager, not in the document. Test every link while you are logged out of your usual browser. Instructions that only work because your laptop remembers a session are not instructions someone else can follow.
The most valuable line in a runbook is often a limit: “Do not restore a database backup without calling me or the designated engineer,” or “You may refund up to $200 for a duplicate charge.” Boundaries let a helper act quickly without granting them authority to make expensive guesses.
You can borrow a lesson from enduring independent software companies such as Basecamp and Balsamiq without pretending to know their internal procedures: staying independent is compatible with taking operations seriously. The size of your manual should follow the risks in your own business, not the org chart of a larger company.
Pay for a backup, not a second founder
There is a wide gap between doing everything yourself and making a full-time hire. For a two-week absence, you may need a trusted person to triage incoming messages and a specialist who can handle a genuine production incident. Those roles can be narrow, paid, and bounded.
Consider a founder spending six hours a week on support and two on routine operations. Hiring a $75,000 employee to cover a possible absence would be a costly answer to an eight-hour weekly workload. A trained part-time support contractor for five hours a week at $45 an hour costs roughly $975 a month. An infrastructure specialist on a small retainer may add a few hundred dollars, depending on scope and availability. Get actual quotes; the point is to buy specific coverage rather than a vague promise of help.
Calculate the expense against a realistic failure. If an uncovered outage would put $3,000 of monthly subscriptions at risk, a modest retainer may be sensible. If the product has 20 customers and none expect same-day support, paid coverage might start with a trusted contractor checking the inbox once daily. Match the arrangement to the obligations customers have actually bought.
Access should be as narrow as the job. Give a support contractor the support tool, approved account views, and a refund limit—not production database credentials. Give an infrastructure backup the minimum needed to investigate and restore service, with an auditable path to emergency access. Turn on multifactor authentication and verify that recovery methods do not all terminate at your phone.
Put the arrangement in writing. Specify the coverage window, response target, hourly or retainer cost, permission limits, and what happens if the backup person is unavailable. Pay them for a practice session before relying on them. Someone who has never opened your support queue is not coverage simply because their name appears in a document.
Run the test while you are still available
Schedule a two-day rehearsal before attempting two weeks. Tell your backup person which dates they are covering. Route ordinary support through the documented process, silence noncritical notifications on your own devices, and intervene only for events your escalation rules classify as urgent. You are testing the system, not proving how good you are at resisting your inbox.
Record four numbers when the rehearsal ends: messages handled without you, messages escalated to you, time to first response for urgent issues, and cash tasks missed or delayed. Add the hours you spent preparing and recovering afterward. If two days away create six hours of cleanup, you have not yet built a two-week-capable operation.
Fix the bottleneck with the smallest durable change. If every escalation concerns one confusing billing action, document or automate that action. If the backup cannot diagnose an alert, improve the alert and runbook. If customers repeatedly need your personal approval for ordinary requests, define a safe approval limit. A new person is not always the answer; sometimes the product or process is asking for unnecessary human intervention.
Extend the next rehearsal to five business days. If it goes well, try two weeks. During each test, keep an emergency contact route open for genuine incidents. “I can be reached for a production outage” is a reasonable safety net. “I’ll quietly answer every ticket at night” makes the test meaningless.
Let customers know what to expect without announcing that nobody is in charge. A short support auto-reply can state response times and provide a route for urgent service issues. If you have contractual service commitments, check them before changing coverage. Your absence plan should fulfill existing promises, not quietly redefine them.
Keep the system cheaper than the risk
Review the plan once a quarter and after any material change: a new enterprise contract, a payment provider migration, a new hosting setup, or the departure of a contractor. Update the cash calendar and test emergency access. Retire procedures for services you no longer use. An outdated runbook can be worse than none because it creates confidence without capability.
Watch the operating cost. If coverage costs $1,200 a month on $18,000 MRR, that is 6.7% of revenue before it has prevented a single loss. That may be justified for a product with serious uptime obligations; it may be excessive for a low-touch tool with patient customers. Start with the highest-consequence gaps, then spend more only when the obligations or cash at risk warrant it.
The goal is not to make the founder irrelevant. Carrd and Buttondown are examples of how small independent software businesses can have a meaningful place in the market; staying small is a deliberate operating choice, not an excuse to leave every critical decision in one person’s head. Your version of resilience may be a well-funded operating account, four good runbooks, and one trained contractor.
A two-week test gives you a concrete standard: bills get paid, serious problems reach a capable person, and customers receive the service they paid for. If the business passes, time away becomes less risky. More importantly, you have removed a hidden dependency that could otherwise turn an ordinary interruption into a cash crisis.

Leave a Reply
You must be logged in to post a comment.