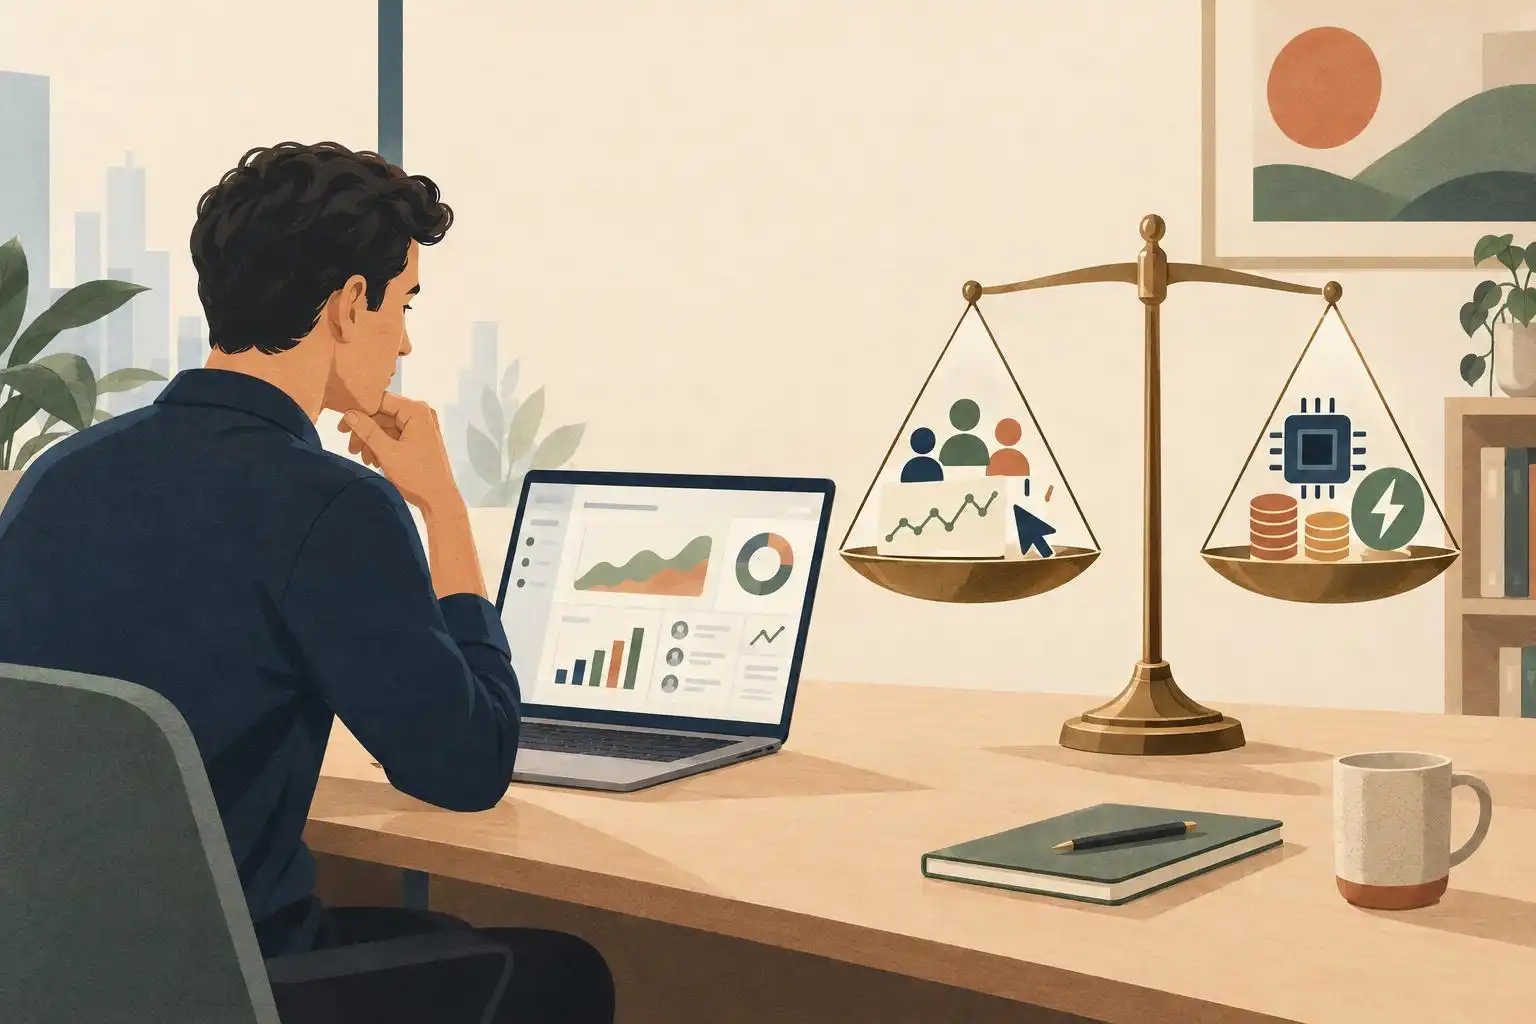

A SaaS free trial used to cost roughly the same whether a prospect clicked twice or explored every feature. An AI free trial can look different: one prospect asks three questions; another runs an agent through thousands of model calls before anyone enters a card number. The second prospect might become your best customer. They might also disappear after consuming more inference than the first customer will buy all year.
That changes the question founders should ask. Not “Can we afford free trials?” but “How much unverified usage can we fund while we learn whether this account is worth acquiring?”
A trial has both a cost and an information yield
Emily Glassberg Sands has described inference costs as making free-trial, refund, and nonpayment abuse more consequential for AI businesses than for software with negligible marginal serving costs. She also recounted a founder who had effectively solved trial fraud by shutting down free trials and sharply limiting credits. Her challenge was the revenue tradeoff: the work to restore trials was still in progress when she discussed it.[1]
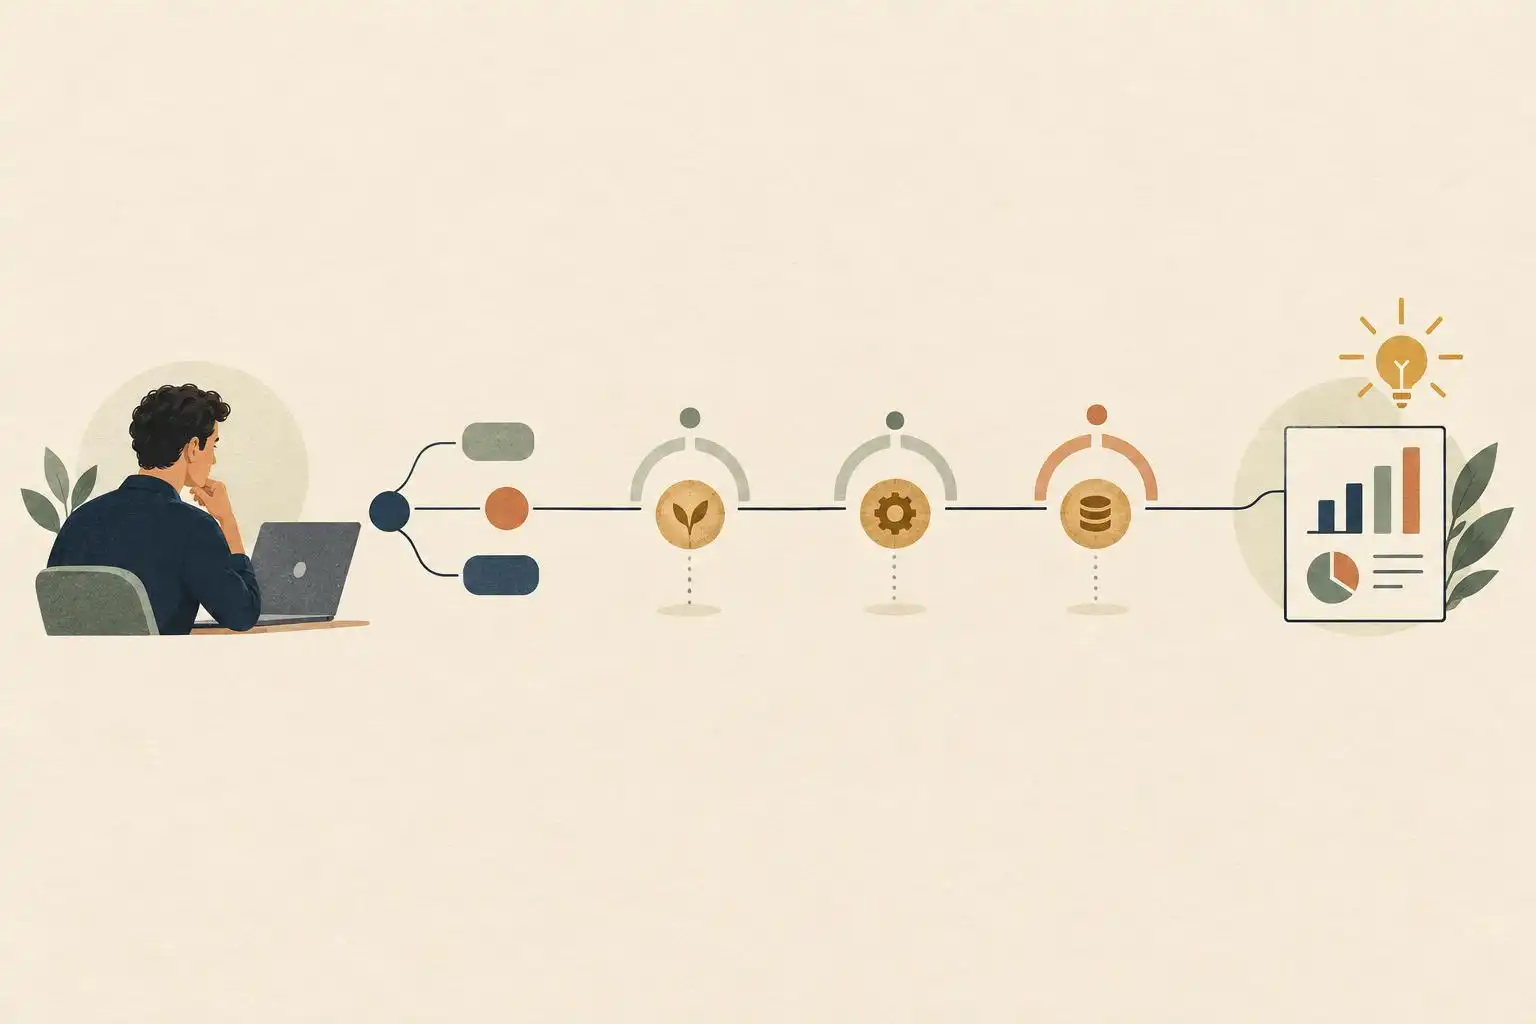
That is the right tension. A trial buys information about demand, but it spends real money to get it. If you eliminate the spend, you may also eliminate the evidence that would have identified your best customers. If you offer unlimited access, you can mistake an expensive signup funnel for a successful one.
The trial should therefore be judged on cost per qualified customer acquired, not just signup-to-paid conversion. A stricter limit may raise conversion among people who reach the paywall while preventing promising users from reaching the moment when the product proves itself. That can make the dashboard look better as the business gets worse.
Underwrite the next action, not the whole account
“Underwriting” here does not mean lending money or collecting a credit history. It means deciding how much additional inference to risk before asking for a stronger signal of intent. That decision can change as the account produces evidence.
For example, an agent that drafts a support reply might receive a small initial allowance. Once a team connects its help desk, tests replies against real tickets, and invites a colleague, the product has more reason to fund a larger evaluation. None of those actions proves the customer will pay. Each makes the next increment of trial spend more defensible than an anonymous signup alone.
A practical trial policy needs three explicit numbers:
- Exposure: the maximum marginal serving cost you will incur before the next checkpoint, not merely the number of credits displayed to the user.
- Evidence: the product action that justifies more exposure, such as connecting a relevant workflow or completing a meaningful test.
- Recovery: the expected gross profit from customers who convert, measured against the cost of all trial accounts, including those that never pay.
The numbers should differ by workflow. A small allowance that demonstrates a writing tool may be useless for a coding agent that needs several iterations to produce something runnable. Equal credits do not create equal opportunities to experience value.
Price the evaluation path into your unit economics
Suppose 1,000 trial accounts each have a $4 initial inference-cost ceiling. One hundred reach a meaningful workflow checkpoint and receive up to $16 more. The maximum exposure under that policy is $5,600: $4,000 for initial access plus $1,600 for expanded evaluations. That is a budget, not a prediction of actual spend.
Now compare cohorts by gross profit after serving costs, not first-month revenue alone. If 40 accounts convert and generate an expected $300 each in future gross profit before trial costs, the cohort has $12,000 available to cover acquisition and trial spend. If only ten convert, the same trial design becomes difficult to justify. Both outcomes can produce exciting product demos; only one supports the budget.
Actual costs will vary with model choice, caching, tool calls, and user behavior. Sands has also described token billing as a way to respond to changing upstream inference costs: falling costs can make fixed prices uncompetitive, while rising costs can damage unit economics.[1] A trial policy set once and forgotten has the same vulnerability. Its exposure ceiling should be expressed in cost, then recalculated when the serving stack changes.
Test whether guardrails protect profit or merely hide demand
Do not ship a tighter trial and declare victory because average inference cost per signup fell. Run a controlled comparison where feasible. Track cost per signup alongside activation, paid conversion, and retained gross profit per acquired customer. Split out suspected abuse, but also inspect legitimate users who hit the limit just before completing a useful task.
This is not an academic distinction. A Replit growth data-science job posting explicitly calls for modeling credit consumption, conversion, and the behavioral effects of pricing and limits in a freemium, usage-based product. It also calls for short-term proxy metrics validated against long-term retention and revenue.[8] The posting does not establish which limits work; it shows why consumption and conversion cannot be analyzed separately.
When a user reaches a cost checkpoint, give them a legible choice. They can verify a payment method, move to a paid evaluation, or wait for an allowance reset. Explain what the limit measures. A mysterious “you’re out of credits” screen turns a risk control into a trust problem.
The first invoice is not the first pricing decision
Billing teams are already being asked to implement usage-based launches quickly. A Stripe listing for a Metronome AI-native solutions architect describes hands-on work across configuration, integration, and technical launch for fast-moving AI companies.[5] That infrastructure matters, but the pricing decision begins earlier: at the moment you decide how much costly work the product will perform before the buyer commits.
Treat that decision as a repeatable acquisition policy. Fund enough usage for a prospect to reach a credible result. Increase the allowance when behavior supplies a reason. Measure the full cohort’s cost against the gross profit of customers you actually keep. The goal is neither a free trial that feels free to finance nor a locked-down demo that never proves the product. It is a trial whose risk you can explain—and whose return you can measure.
References
- Emily Glassberg Sands — Latent Space — https://latent.space/wiki/emily-glassberg-sands-9c2d5a95
- Solutions Architect, Metronome (AI Native) at Stripe | Andreessen Horowitz — https://jobs.a16z.com/jobs/stripe/8368260–solutions-architect-metronome-ai-native
- Data Scientist, Growth at Replit | Andreessen Horowitz — https://jobs.a16z.com/jobs/repl.it/1066b974-3cd8-42cf-a11c-a4217c06f70f–data-scientist-growth


Leave a Reply
You must be logged in to post a comment.